™
From bare metal to billable tokens.
ServeLLM is the complete enterprise suite that turns a GPU cluster into a sovereign AI cloud – sold commercially under your brand, or kept fully isolated for internal use. Your data, your jurisdiction, your currency.
- To switch from OpenAI
- 1 line
- Priced, billed and collected in rupees
- PKR
- From pilot to first paying tenant
- 30 days
The problem today
Every AI roadmap runs through someone else's data center.
Dollar-billed
Foreign clouds invoice in USD – FX volatility and card-network tax on every token.
Offshore
Data residency that breaks compliance the moment a prompt crosses a border.
Monolith
One model, one vendor – for every workload, regardless of fit or cost.
The suite
Everything between your GPUs and your paying customers.
Start from bare-metal or virtual servers. Finish with a running, billing, multi-tenant AI cloud. Three components, one system.
Platform Dashboard
The storefront and control room: organizations, users, API keys, usage and revenue. An ops console for you, a self-serve portal for every customer.
Engine
Routes every request, meters every token, prices, bills, logs and audits – the API your customers call and the dashboards you watch.
Agent
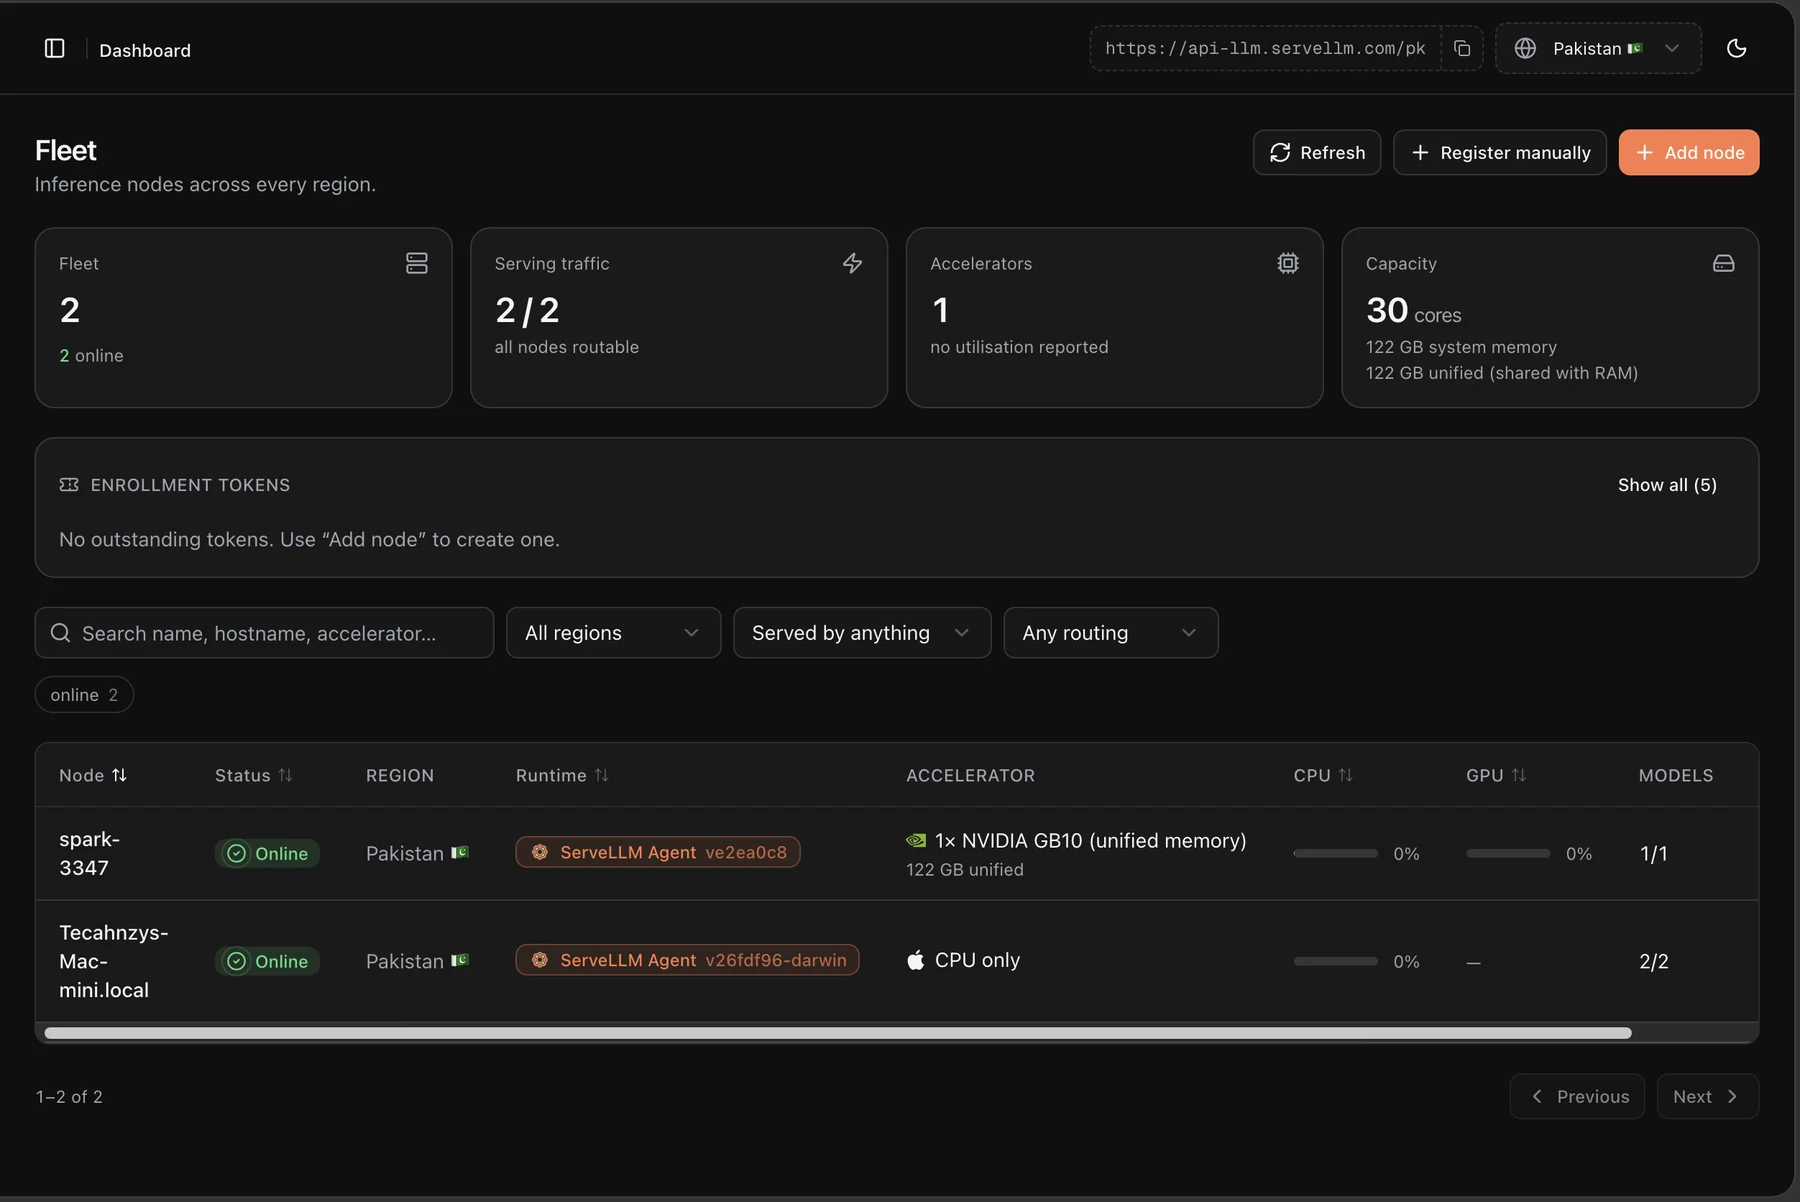
Installs on each server: bootstraps the node, keeps models loaded and current, streams telemetry and serves the tokens.
Built yourself, this platform is 12–18 months of engineering before the first rupee of revenue. With ServeLLM it runs on your metal in days.
Who it's for
Built for teams that need AI sovereignty.
Whether you're launching a commercial AI cloud or keeping inference fully isolated inside your network – these are the operators ServeLLM is built for.
Sovereign Cloud Operators
Stand up a commercial AI cloud in your country – branded as yours, billed in local currency.
Telcos & ISPs
Ship AI APIs and copilots to enterprise and consumer customers – over your own network.
Governments & Public Sector
Ministries, regulators, defense – citizen services and internal copilots, no data offshore.
Banks & Financial Institutions
Run inference inside your perimeter for regulated, audit-heavy workloads and internal copilots.
Healthcare & Life Sciences
Patient, trial, and clinical data never leaves your jurisdiction – for research, ops, and care.
Enterprises & Conglomerates
Internal copilots and document AI for teams that can't put proprietary IP in a foreign cloud.
Platform & developer experience
One endpoint. Any model.
ServeLLM routes every request across Qwen, Llama, and more – through one OpenAI-compatible API. Pick the right model per workload, observe everything, scale elastically.
Change one line. Keep your stack.
Any OpenAI SDK, in any language, points at ServeLLM by changing a single base URL.
import openai client = openai.OpenAI( api_key="YOUR_API_KEY", base_url="https://api-llm.servellm.com/v1" # ← change just this one line) response = client.chat.completions.create( model="qwen3:0.6b", messages=[{"role": "user", "content": "Hello!"}])AI sovereignty
AI sovereignty by data, jurisdiction, and currency.
Your data stays in-country. Your money stays in your currency. Your audit trail stays with you – not on someone else's terms of service.
In‑country inference. Open‑weight models. Your keys.
In-region inference
Deploy in jurisdictions your regulators recognise – citizen data and prompts never leave the country.
Open‑weight, no lock‑in
Qwen, Llama, and more – portable weights you can move if you ever need to.
Role-based keys & audit logs
Scope access by team, inspect every request, prove compliance on demand.
Billed in your currency. Settled on local rails.
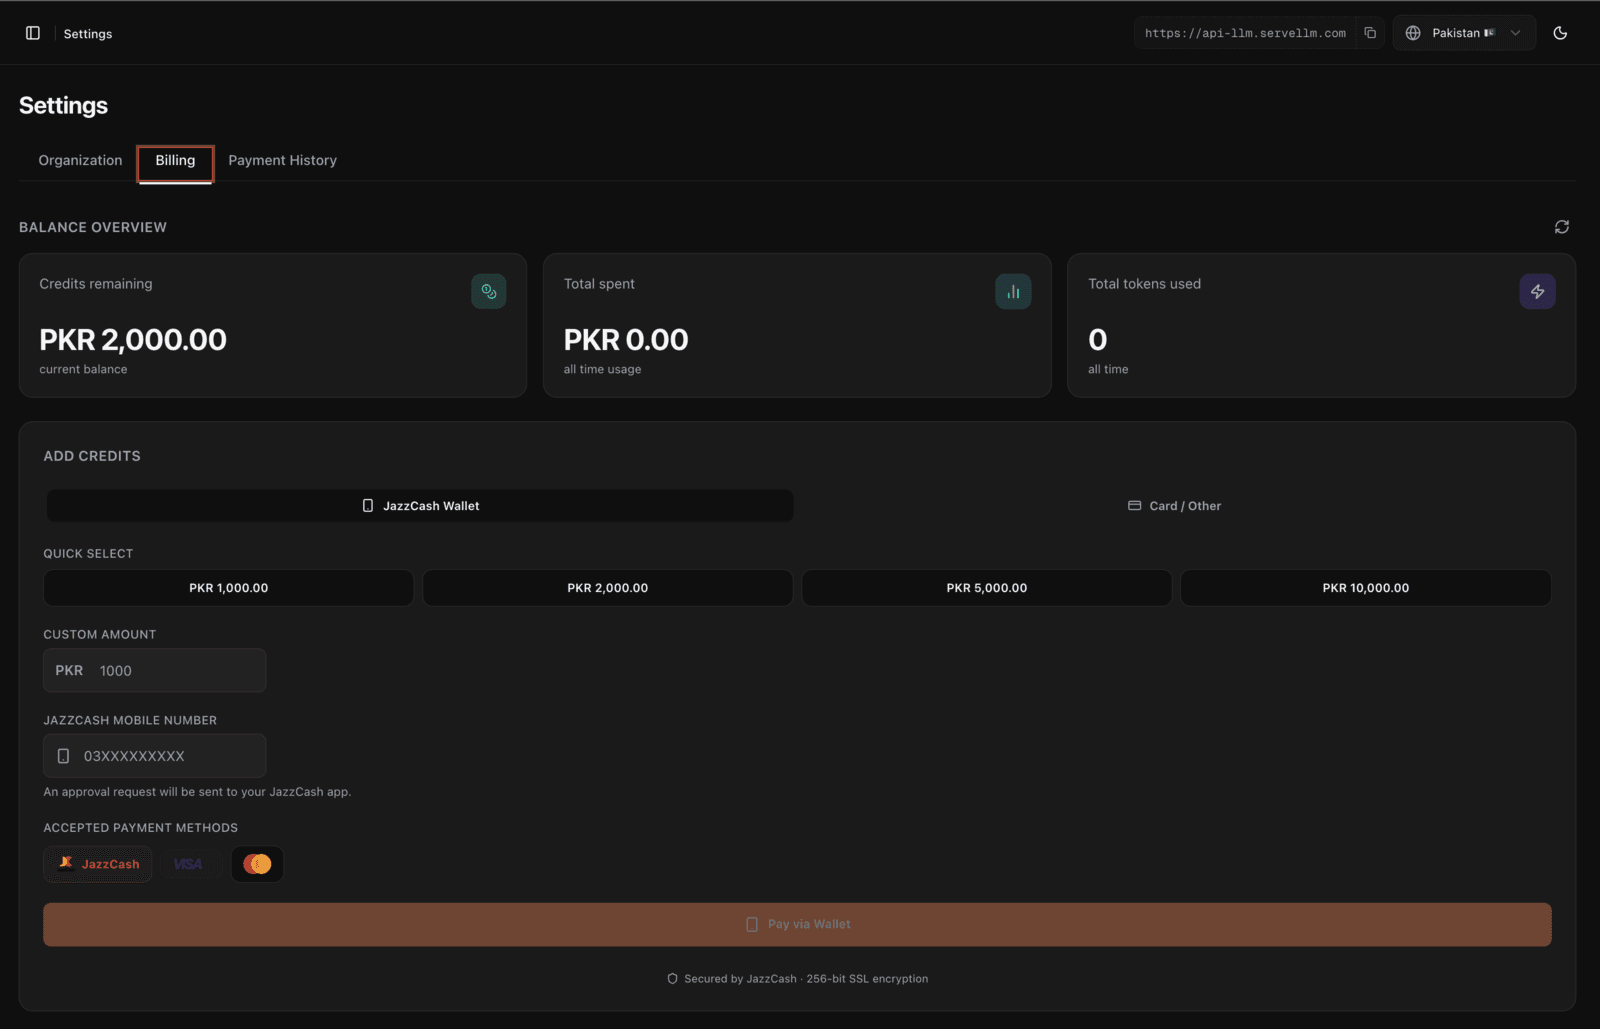
Native local-currency billing
Invoices issued in your currency, with tax line items ready for filing.
Zero FX leakage
No dollar-quota friction, no card-network conversion fees, no mid-month spread shocks.
Pay how your region pays
Raast, 1LINK, JazzCash, Easypaisa, NayaPay, bank transfer or cards – prepaid credits or invoices on your letterhead.
The platform
Everything your AI team needs, on one dashboard.
Multi-Model API
Switch between Qwen, Llama and more with a single line of code – OpenAI-compatible.
Real-time Streaming
Token-by-token streaming on a low-latency, region-local inference layer.
Playground
Compare model outputs side-by-side, tune prompts – without writing a line of code.
Request Logs & Usage
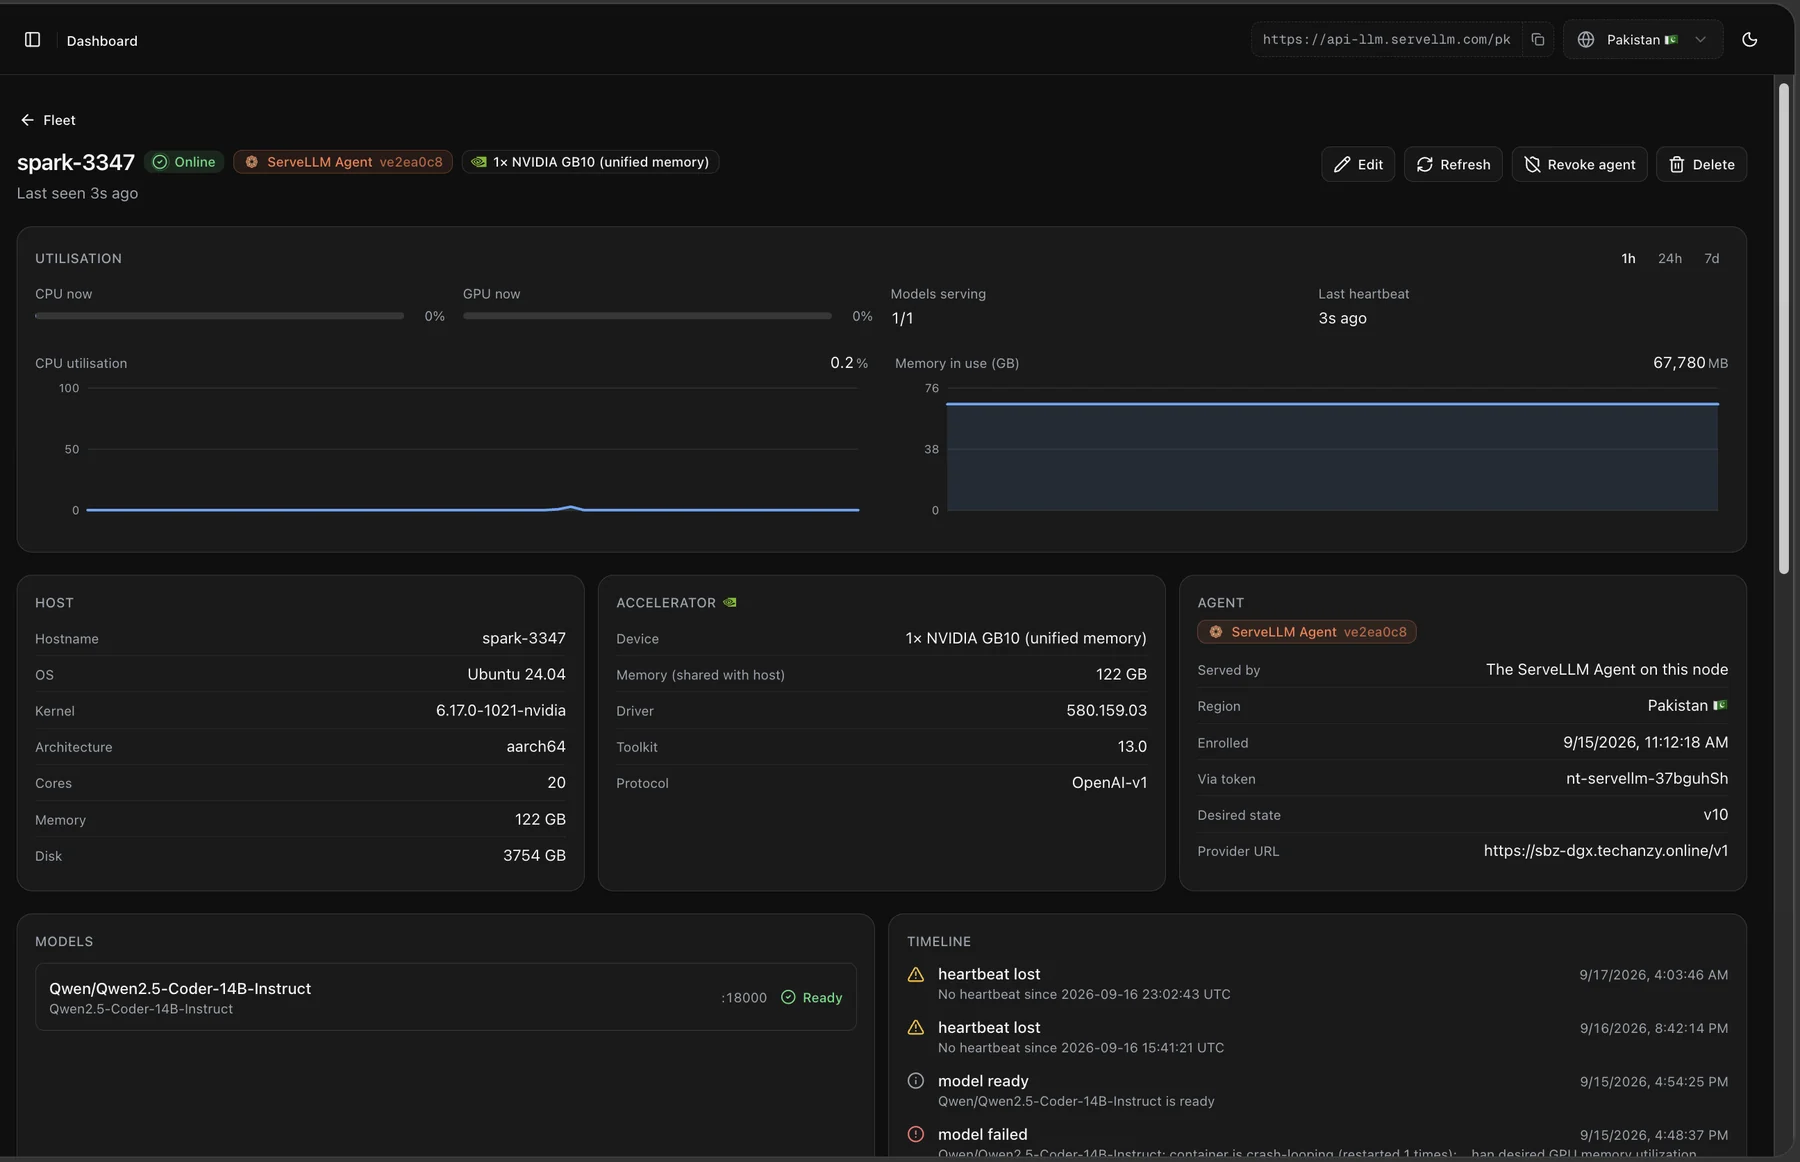
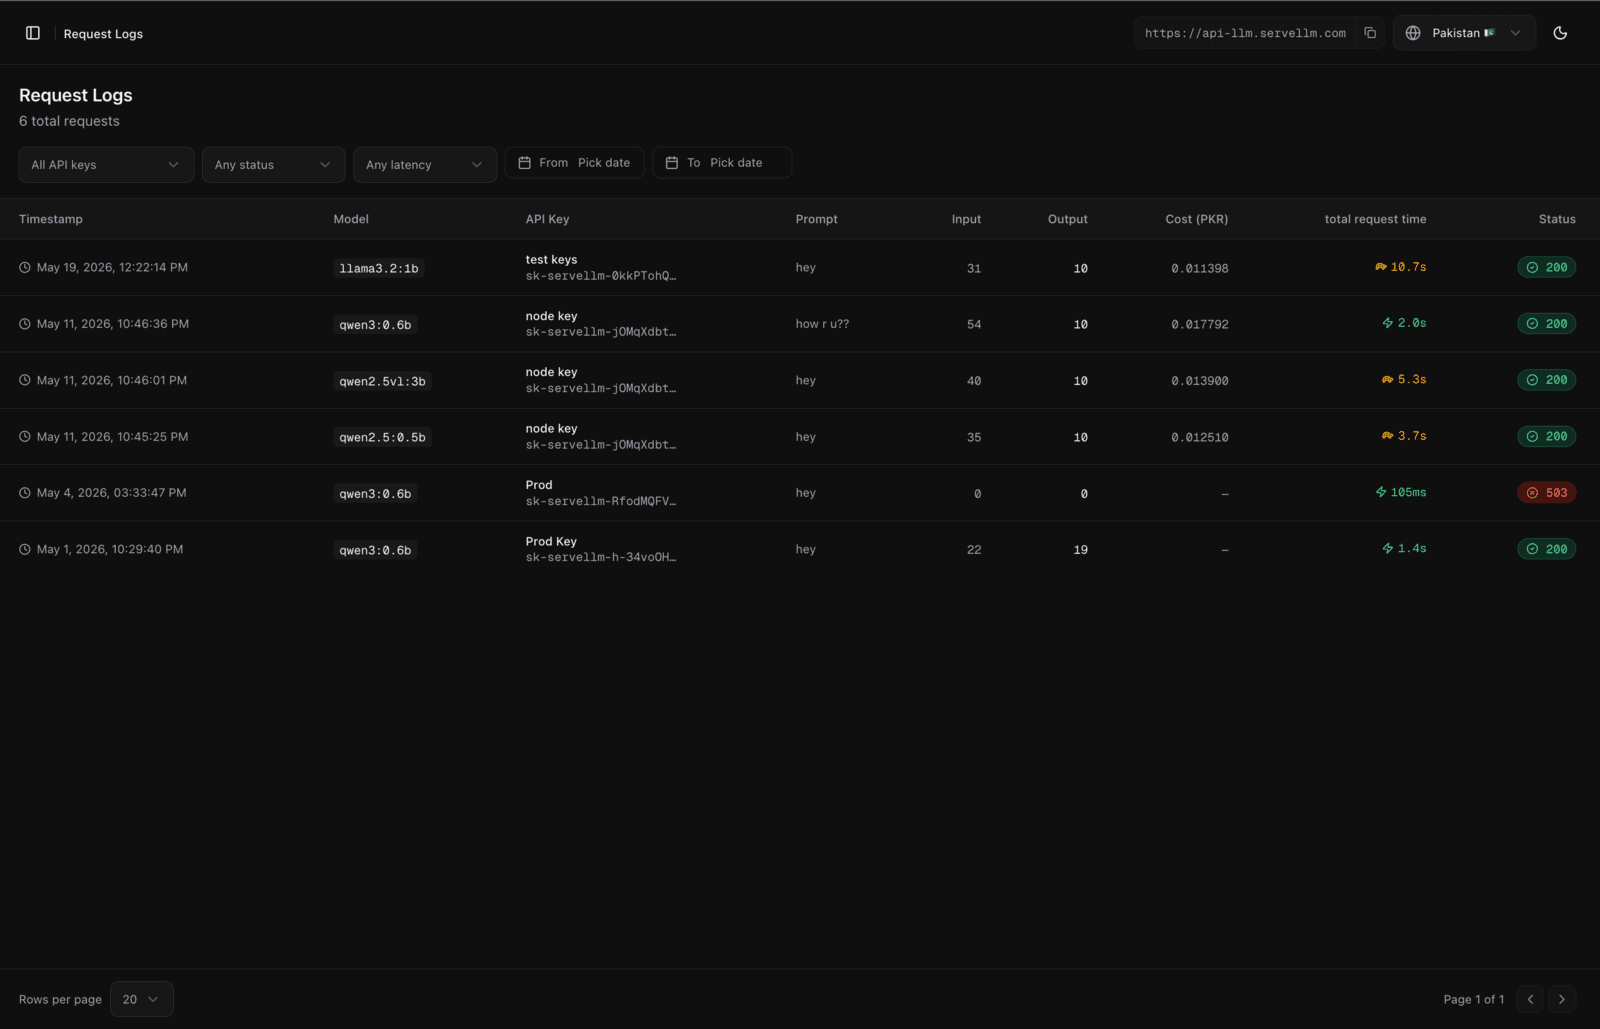
Inspect every request, monitor tokens, track spend – directly in the dashboard.
API Keys & Members
Scope access, invite teammates, and govern with role-based permissions.
AI Sovereignty Built-in
In-region serving with audit logs, residency controls, and local-currency billing.
LLM Firewall
Every prompt and completion screened at the gateway for injection, data leakage and unsafe output – set once per organization.
Fine Tuning
Train an open model on your own data on regional hardware, and call it through your existing API keys. The weights stay yours.
Sample use case
A government loan, decided by AI – without the documents leaving Pakistan.
A demo small-business finance portal. The applicant uploads a CNIC and a bank statement; a model reads them, verifies income and issues a decision in one sitting.
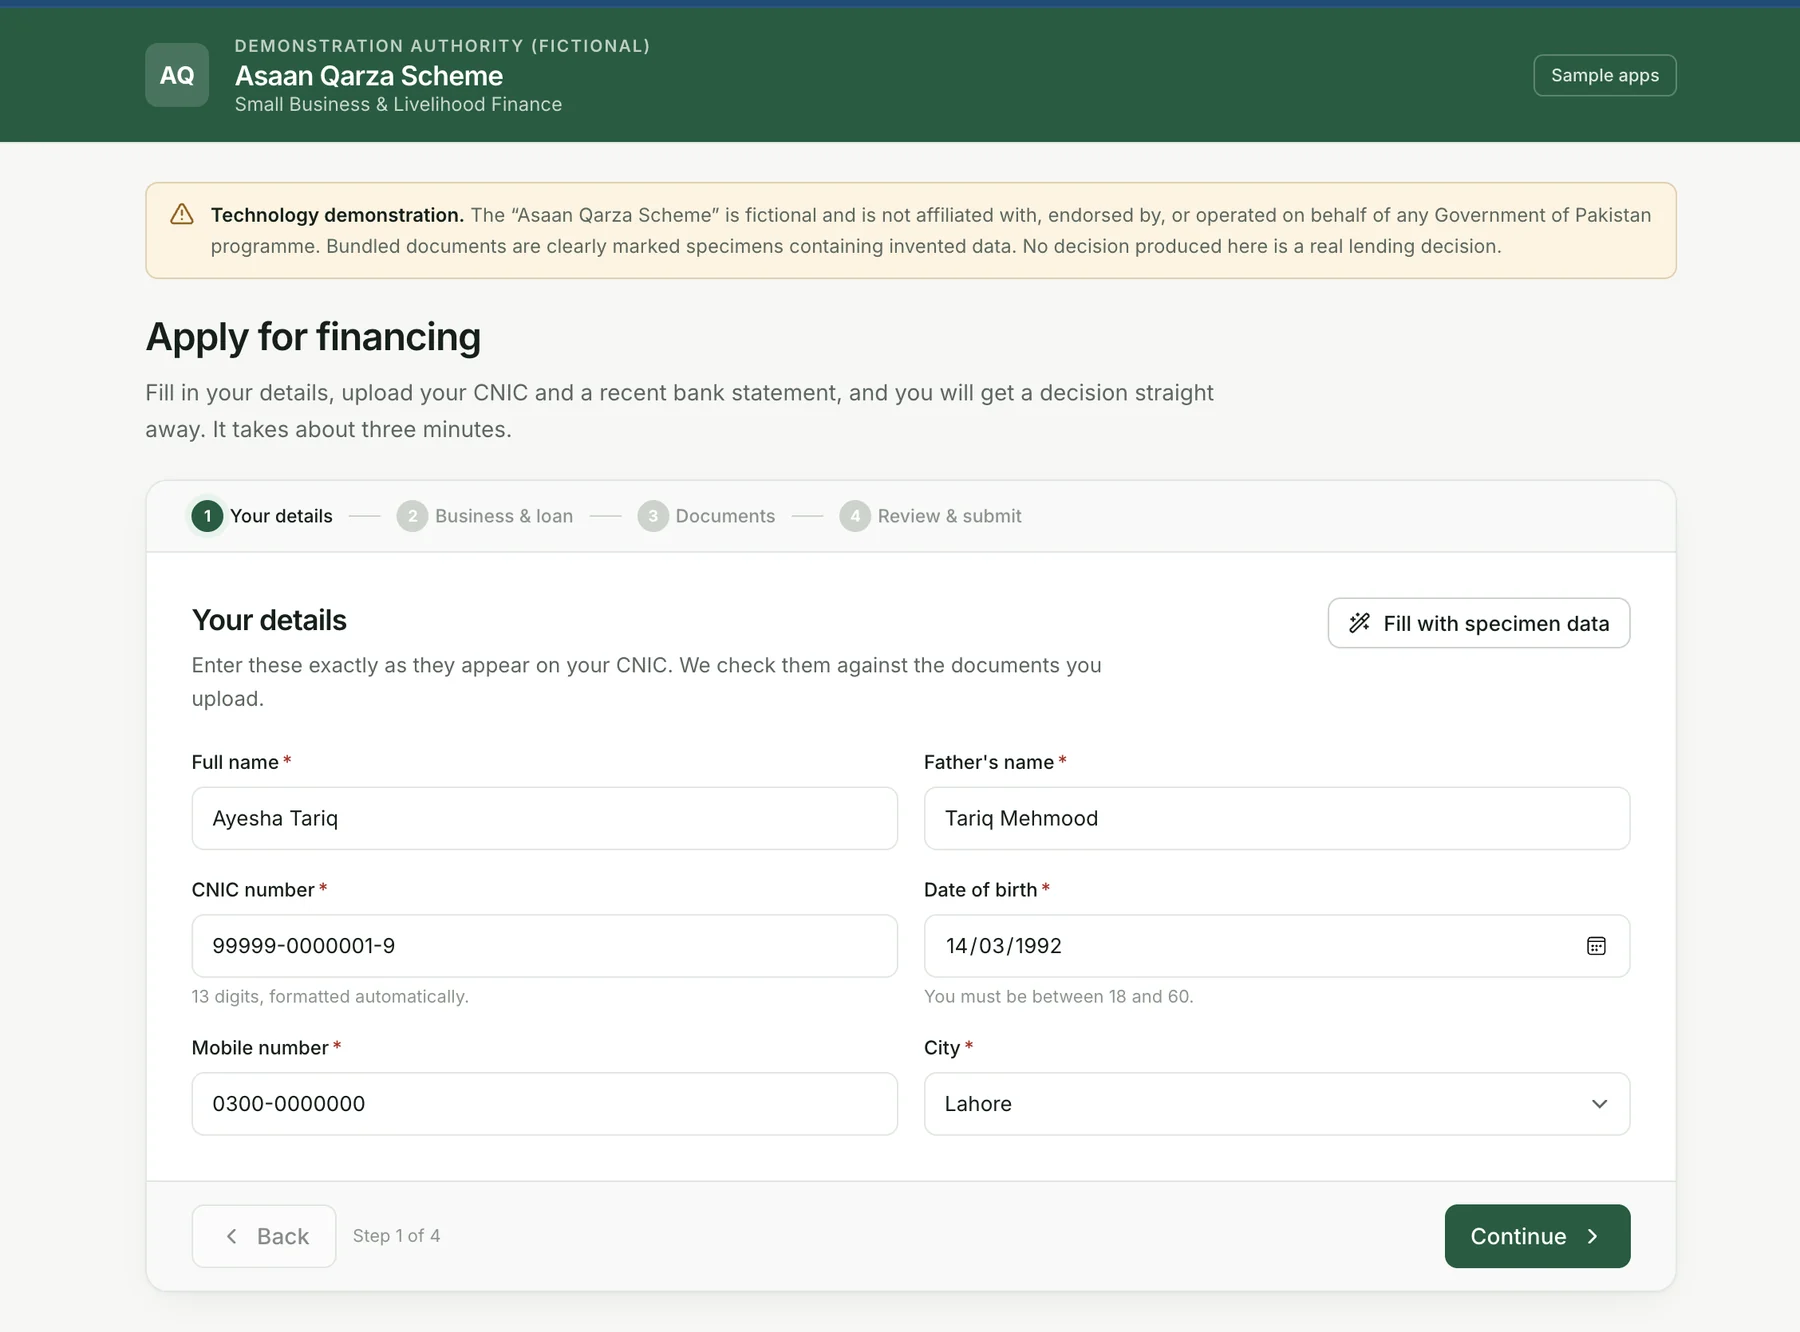
01Details & loan request
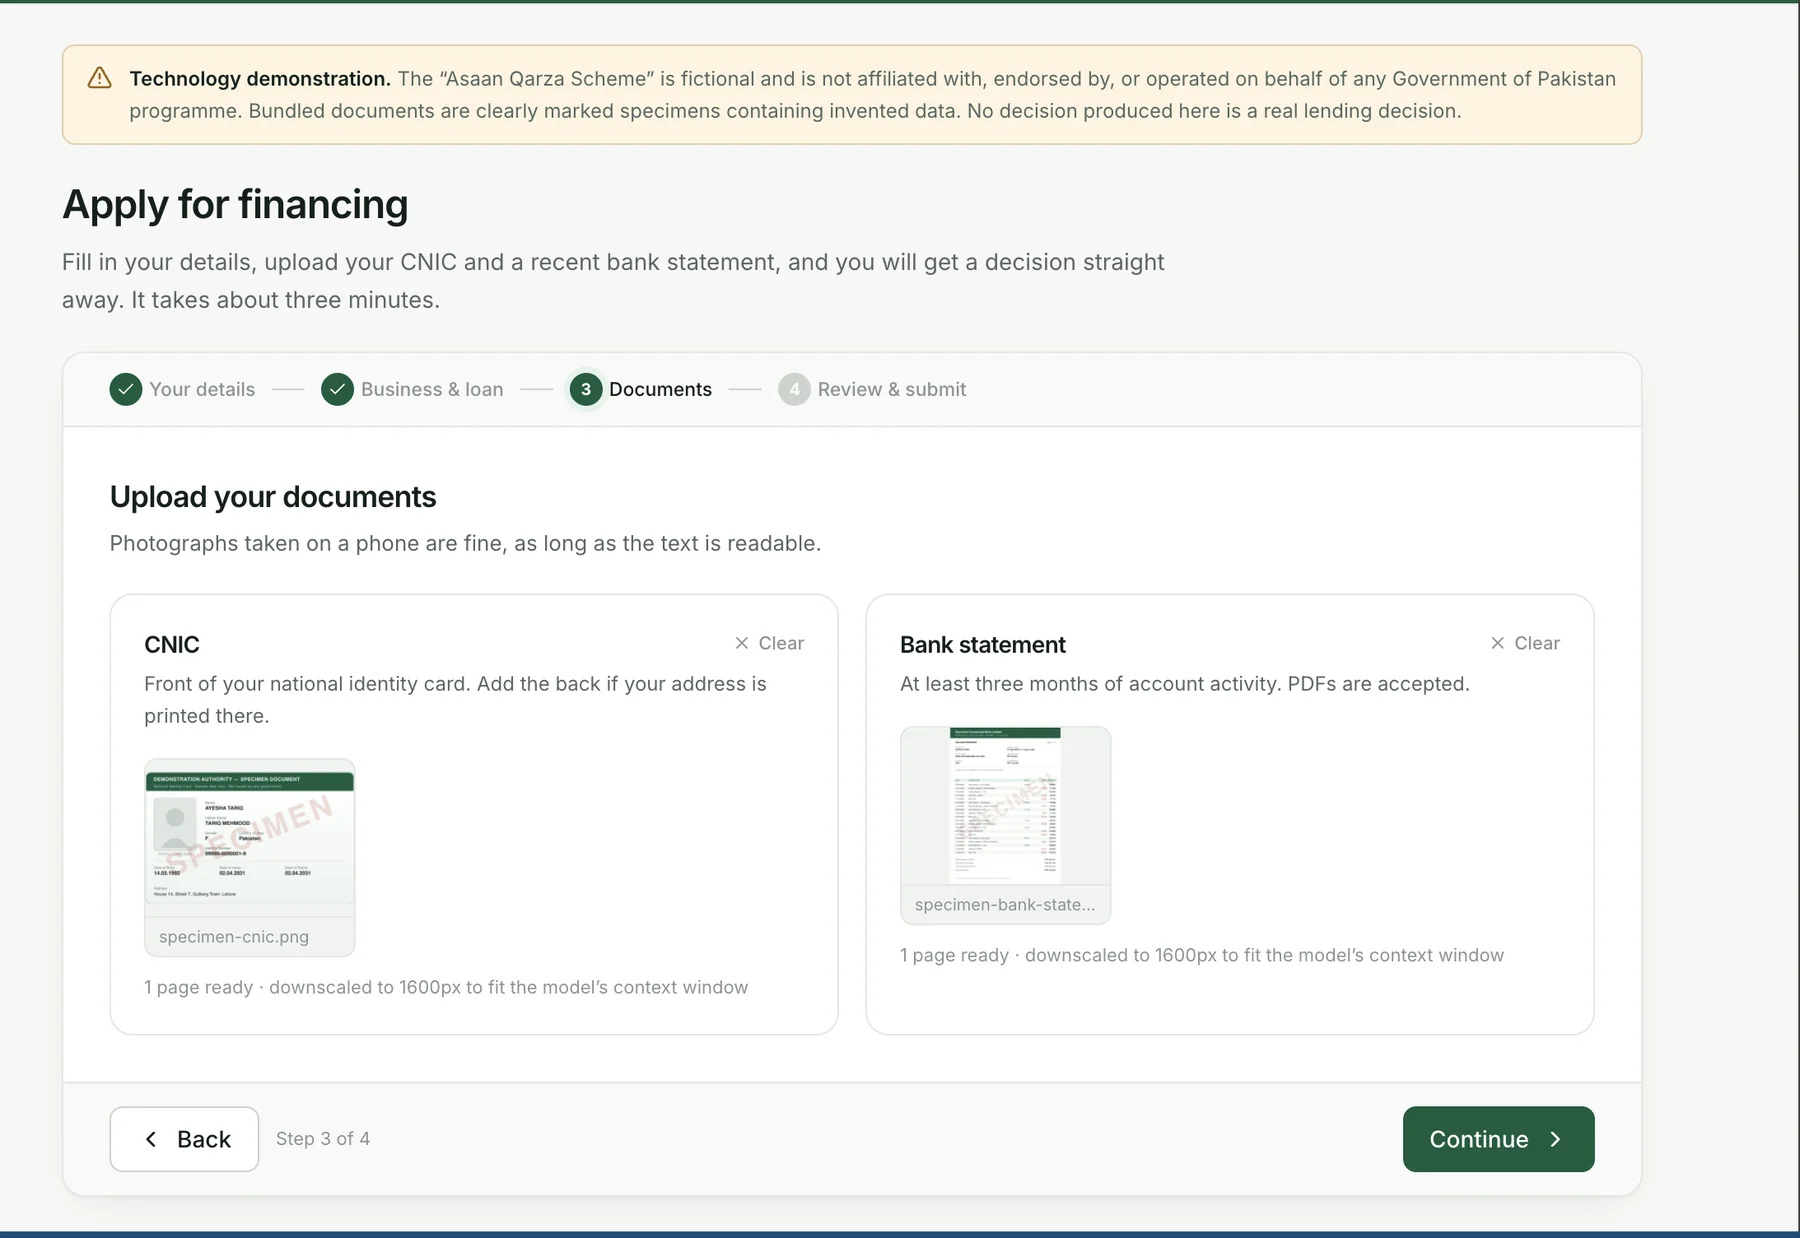
02CNIC & bank statement
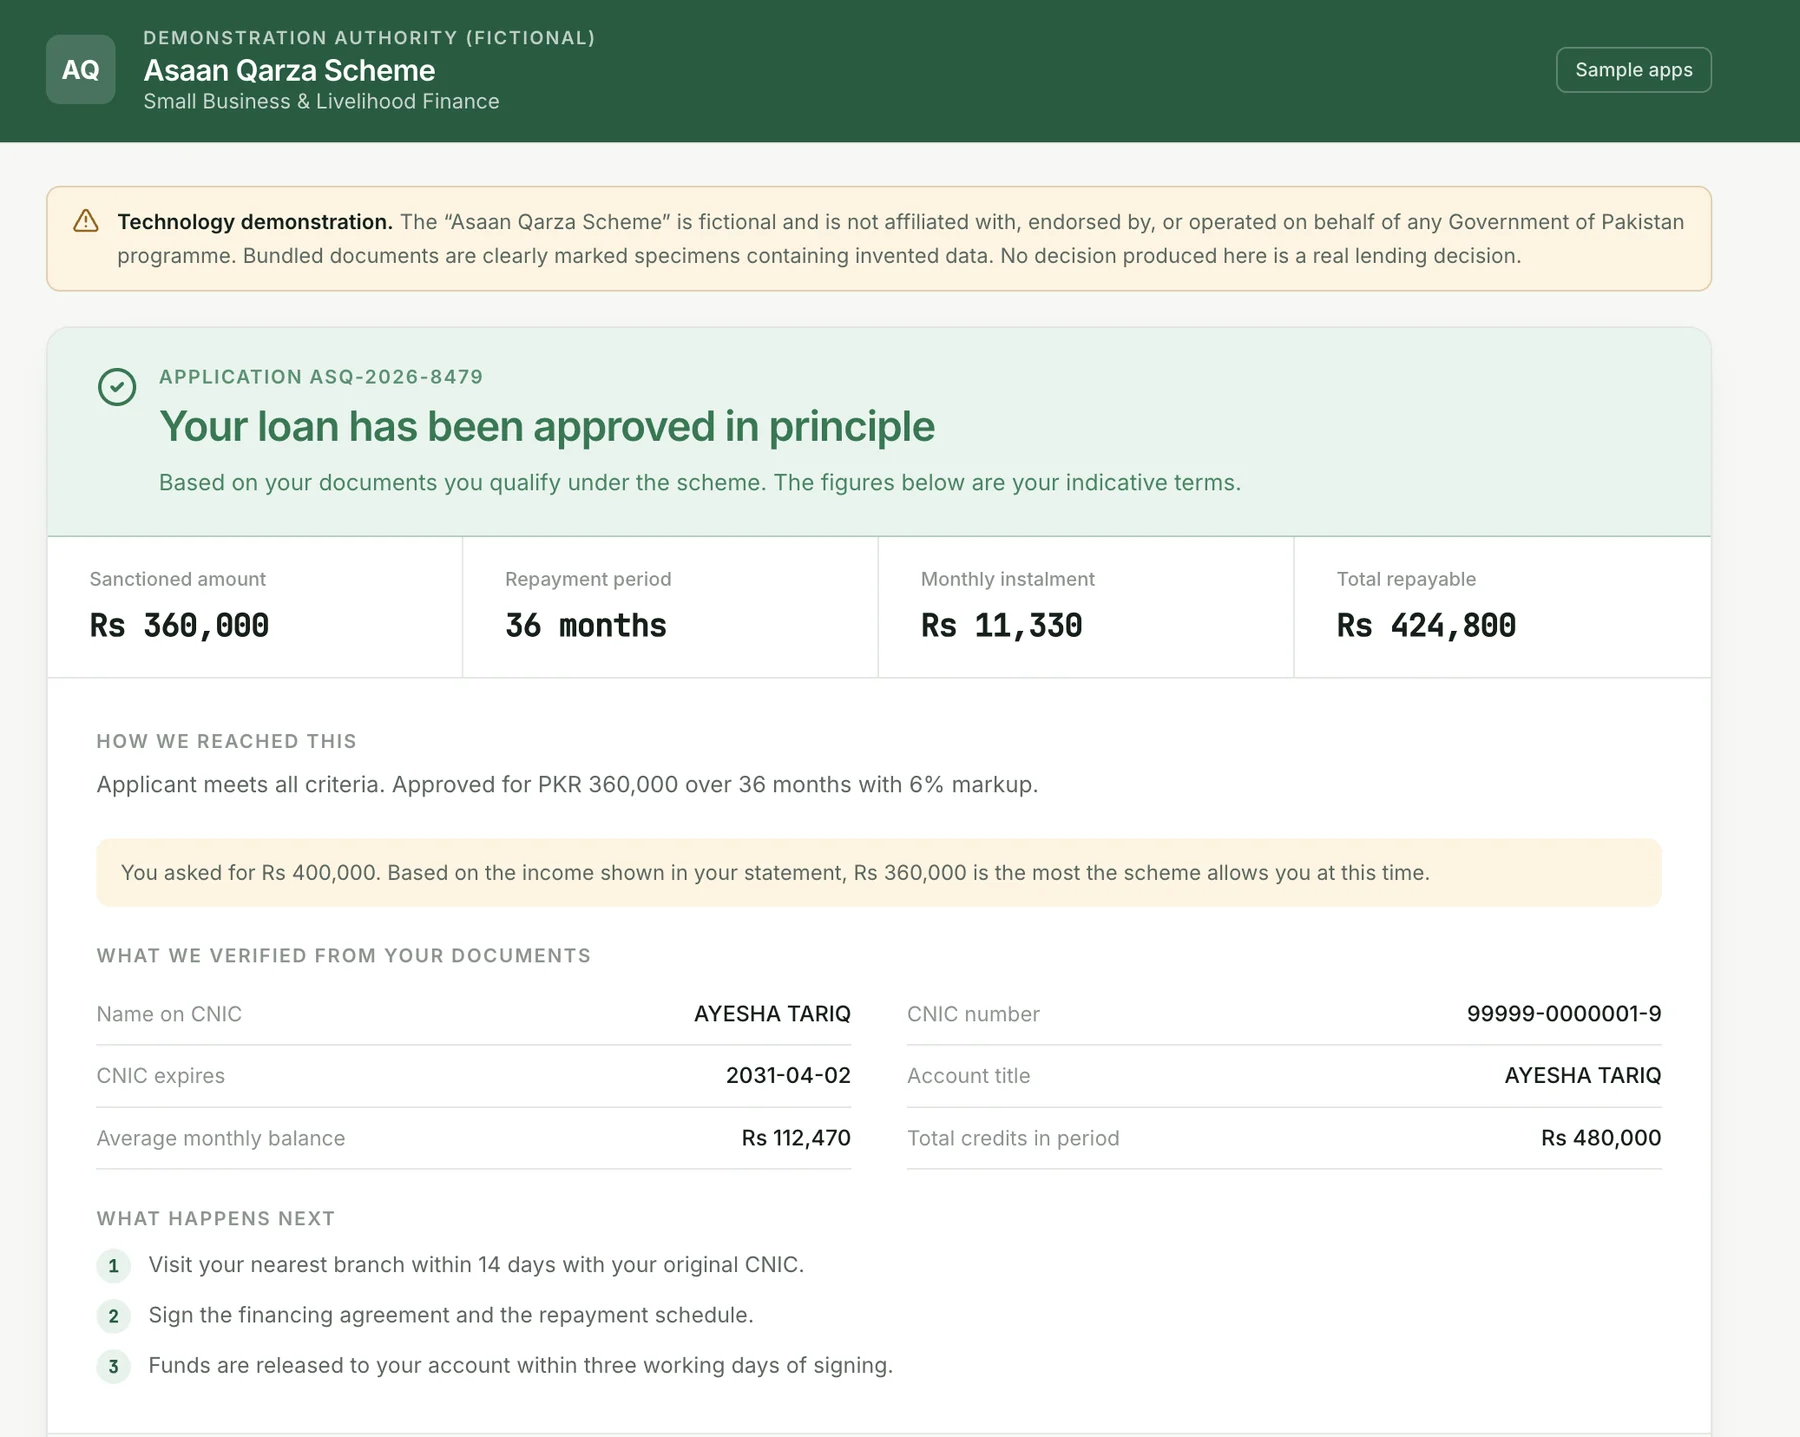
03The AI decision
The "Asaan Qarza Scheme" is a fictional demo with specimen documents, not affiliated with any government programme.
Same app, one switch
Same application. Same decision. Different country.
| Compared on | OpenAI abroad | ServeLLM in-country |
|---|---|---|
| Where the CNIC & statement went | OpenAI abroad:United States | ServeLLM in-country:Your node |
| Latency | OpenAI abroad:5.1 s | ServeLLM in-country:3.4 s |
| Cost per application | OpenAI abroad:$0.041 ≈ Rs 11.5 | ServeLLM in-country:Rs 2.8 |
| Billed in | OpenAI abroad:USD card | ServeLLM in-country:PKR invoice |
| Audit trail | OpenAI abroad:Vendor logs, abroad | ServeLLM in-country:Full log, on your Engine |
| Data protection | OpenAI abroad:Cross-border transfer | ServeLLM in-country:Never leaves Pakistan |
Latency and cost are illustrative targets for a comparable open model on a production GPU node; the sample app and its documents are fictional specimens.
Deployment
Day 1 to first revenue in 30 days.
The pilot: 10 nodes, deployed by our team, running alongside your existing workloads with zero disruption.
- 01 · Week 1
Agents live
Our team installs the Agent on 10 nodes. Models loaded, cluster serving internally by Friday.
- 02 · Week 2
Platform live
Dashboard up, pricing configured, billing connected. Your team trained on the console.
- 03 · Week 3
First tenants
Pilot customers onboarded – real traffic, real usage data, first invoices generated.
- 04 · Week 4
Review & scale
Utilization and revenue numbers on the table. Together we shape the full rollout.
Commercials
Three ways to partner.
No commitment up front – the 30-day pilot gives us both the numbers to pick the right structure.
Platform license
An annual license per node. You operate the platform and keep 100% of token revenue.
Revenue share
Minimal upfront. We take a share of token revenue – we only earn when your cloud sells.
Fully managed
We run your AI cloud end to end under your brand. You provide the metal; we do the rest.
Light up your first 10 nodes. Or point your app at ServeLLM.
Running GPUs? We'll scope a 30-day pilot with success criteria agreed up front. Building an AI product? Change one line and keep your stack – we'll help you move over.
Book a call